

Underwriters are hired to assess risk, price it accurately, and build strong broker relationships. Instead, a large share of their day disappears into re-keying submission data and reconciling it across disconnected systems.
This isn't a minor inefficiency. Underwriters spend over two hours daily on manual data entry, according to recent data from hyperexponential. That's time pulled directly from risk analysis and pricing decisions.
This article covers where that time actually goes, why the cost compounds beyond the hours lost, and what a realistic fix looks like without replacing your core systems.
What Manual Data Entry Actually Costs Underwriters
Two hours a day on manual data entry adds up to roughly a quarter of a standard workday, every day, for every underwriter on your team. Multiply that across a full underwriting staff and the number stops looking like a nuisance and starts looking like a structural cost.
The paradox is that this is usually invisible on a P&L. No line item says "manual data entry." It shows up instead as slower quote turnaround, inconsistent decisions, and underwriters who feel more like administrators than risk experts.
The time breakdown
Most of the lost time isn't spent on judgment calls. It's spent getting data into a usable state before judgment can even begin.
Why this is worse than it looks on paper
A few minutes lost per submission seems small in isolation. Across hundreds of submissions a month, it becomes the single largest constraint on how much business an underwriting team can actually process.
Where the Time Actually Goes
Submission data rarely arrives ready to use. Understanding exactly where it gets stuck is the first step toward fixing it.
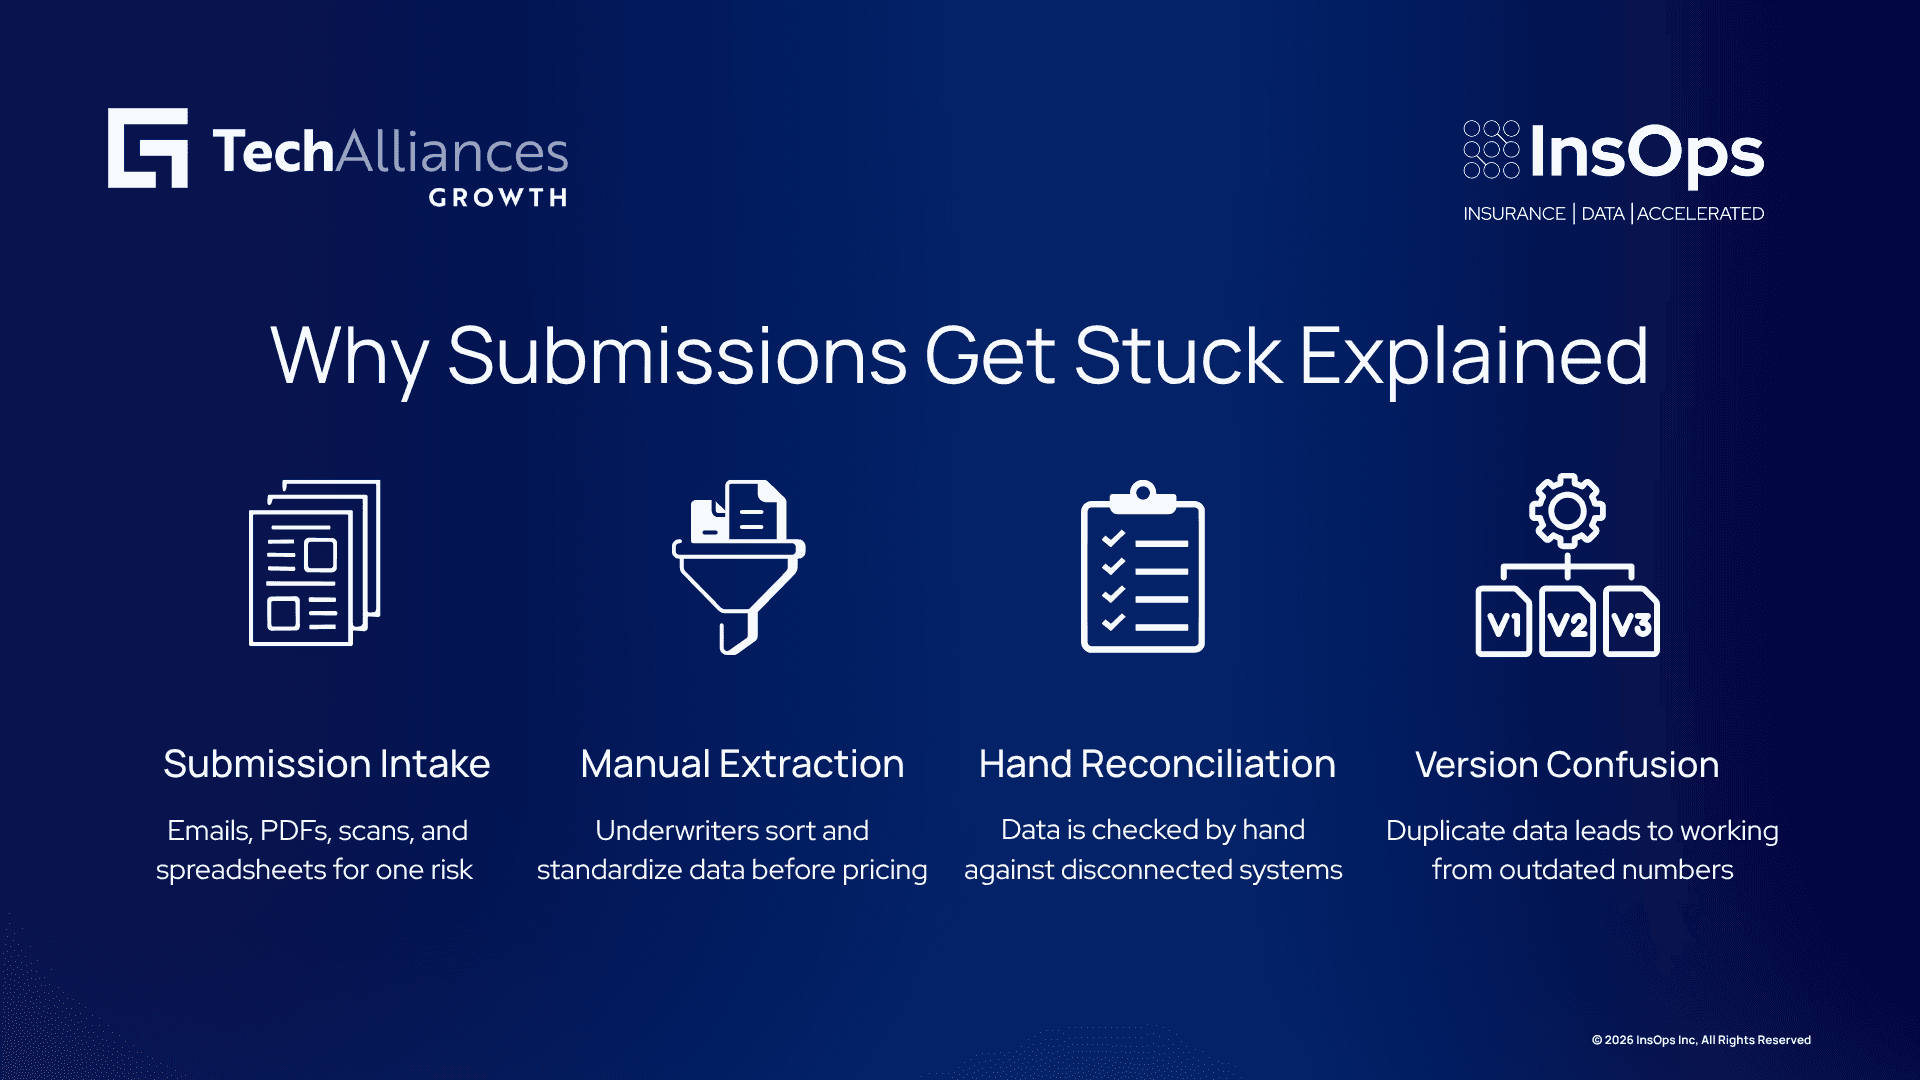
Submission intake in inconsistent formats
Broker submissions land as emails, PDFs, scanned forms, and spreadsheets, often for the same risk. Underwriters have to manually sort, extract, and standardize this information before pricing can start.
Manually reconciling data against core systems
Once extracted, that data has to be checked against what's already in policy, billing, and underwriting systems. When those systems don't talk to each other, that reconciliation is done by hand.
Version control problems
When the same risk data lives in a spreadsheet, an email thread, and a core system at once, it's easy for an underwriter to work from an outdated number without realizing it.
Why This Compounds Beyond Lost Hours
The direct time cost is only part of the problem. Manual data entry introduces downstream effects that are harder to see but more expensive to fix.
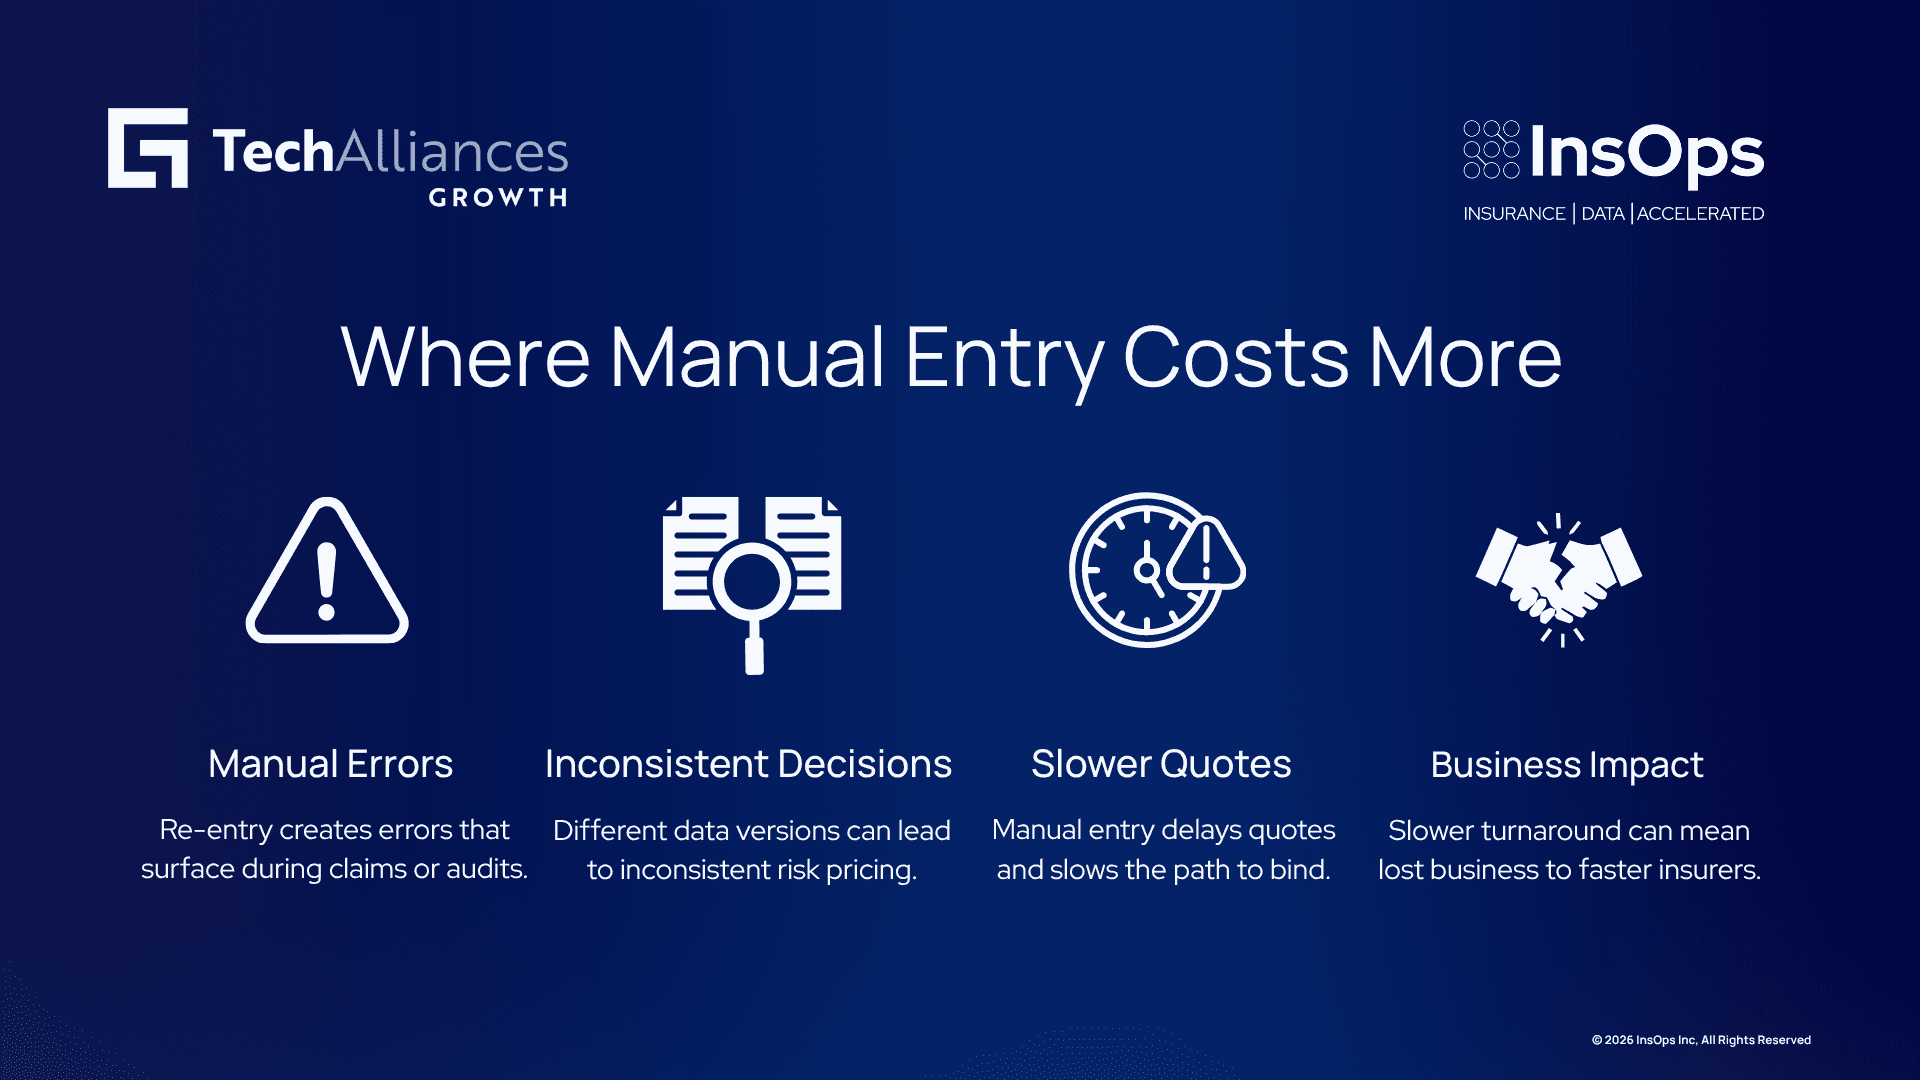
Error rates from manual re-entry
Every manual re-entry step is a chance for a transposed number or a missed field. These errors often surface later, during claims or audits, when they're far more costly to correct.
Inconsistent decisions across underwriters
When underwriters work from different versions of the same data, similar risks can get priced differently. That inconsistency is hard to explain to regulators, brokers, or your own leadership team.
Slower quote-to-bind cycles
Every hour spent on data entry is an hour not spent getting a quote out the door. In a competitive market, slower turnaround means lost business to insurers who respond faster.
What a Better Workflow Looks Like
The fix isn't necessarily a system replacement. It's adding a layer that maps and validates data before it reaches your underwriters, so the re-keying step disappears without disrupting the systems already in place.
Manual data entry workflow | Data mapping and validation layer | |
|---|---|---|
Where submission data comes from | Emails, PDFs, spreadsheets, multiple formats | Same sources, ingested and normalized |
Who re-keys it | Underwriter, by hand | System maps and validates, human confirms |
Time to usable data | Hours per submission | Minutes per submission |
Error source | Manual re-entry, version control | Flagged inconsistencies for human review |
What stays the same, what changes
The underwriter's judgment stays exactly where it belongs, on the final call. What changes is everything upstream of that decision: the extraction, the mapping, and the cross-checking that currently eat up the workday.
How InsOps Helps
InsOps builds an insurance-trained AI that assists with mapping and validating submission data before it reaches your underwriters. LiLa, our insurance-trained LLM, runs inside your own environment, so PII and PHI never leave controlled infrastructure. A person reviews and confirms every mapped data point before it moves into your underwriting workflow.
Our Integration Gateway connects directly to Guidewire PolicyCenter, UnderwritingCenter, and PricingCenter, so submission data flows into your existing systems without custom engineering or a rip-and-replace project.
If you are evaluating how to cut the hours your underwriters lose to manual data entry without adding new compliance or data exposure risk, contact us to talk through what this could look like for your operation.
Frequently Asked Questions
What is manual data entry in underwriting?
It's the process of an underwriter manually reading submission documents (emails, PDFs, spreadsheets) and typing that information into pricing models and core systems by hand.
Why does manual data entry hurt underwriter productivity?
It pulls underwriters away from risk assessment and into repetitive administrative work. That lost time comes directly out of their capacity for pricing and risk decisions, the exact hours that should be spent on judgment calls instead of retyping submission data.
How can an insurer start reducing manual data entry without replacing core systems?
Add a data mapping and validation layer between incoming submissions and your existing systems. This standardizes and checks the data automatically, with a human confirming the result, rather than requiring underwriters to re-key it.
What's the biggest challenge in fixing this?
Submission data arrives in wildly inconsistent formats from different brokers. Any fix has to handle that variability without forcing brokers to change how they submit business.
How do you measure whether it's actually working?
Track hours per submission spent on data entry, time from submission to quote, and error rates in the final risk data. A working fix should move all three in the right direction within the first underwriting cycle or two.
How does AI-assisted data mapping work in practice?
The system extracts and maps submission data into your core systems automatically. An underwriter reviews and confirms the mapped data before it's used for pricing, so the final decision always stays with a person.
How long does it realistically take to see results?
Insurers typically see a measurable drop in time spent per submission within the first few weeks of rollout, since the Integration Gateway connects to existing Guidewire systems without requiring a system replacement. Full impact across a whole underwriting team usually takes a full quarter to show up in quote-to-bind metrics.